How speculative decoding increases generation speed
Efficiently processing text with large language models is a central theme in the optimization of artificial intelligence. Once the input has been processed, the generation phase begins, in which the output is built up token by token. This phase is often the bottleneck in practice. To understand how this delay arises and how speculative decoding offers a solution, we first look at the nature of the autoregressive process during inference.
The problem of autoregressive generation
Classic language models generate text in an autoregressive manner. This means the model predicts exactly one new token based on the input context and the tokens already generated. Once the new token has been chosen, it is added to the already assembled sequence, after which the process repeats for the next token.
Although this is mechanically simple, a fundamental efficiency problem arises at the hardware level. Modern graphics processors (GPUs) have thousands of compute cores that can perform calculations in parallel. When processing the initial prompt (the prefill phase), all input tokens are processed simultaneously, allowing the compute cores to be optimally utilized. Once the model reaches the generation phase, however, the entire network must be traversed for each individual token.
At each step, all parameters and weights of the model must be loaded from working memory (VRAM) to the processor's compute cores. Because only one token is processed at a time, a large part of the chip's compute capacity remains unused. Processing speed is not limited by the processor's maximum compute power (TFLOPS), but by memory bandwidth (also known as memory-bound). Retrieving gigabytes of weights takes considerably more time than the actual matrix multiplication for that single token.
The principle of speculative decoding
Speculative decoding is a technique that bypasses this memory barrier by using compute power to reduce the number of memory transfers. The basic concept rests on the assumption that predicting simple or predictable words does not require the full capacity of a model with billions of parameters.
The method uses two different models that work together:
- The draft model: A small, extremely fast model that proposes multiple consecutive tokens (a speculative sequence) with minimal memory load.
- The target model: The original, large language model that must guarantee the quality and accuracy of the final result.
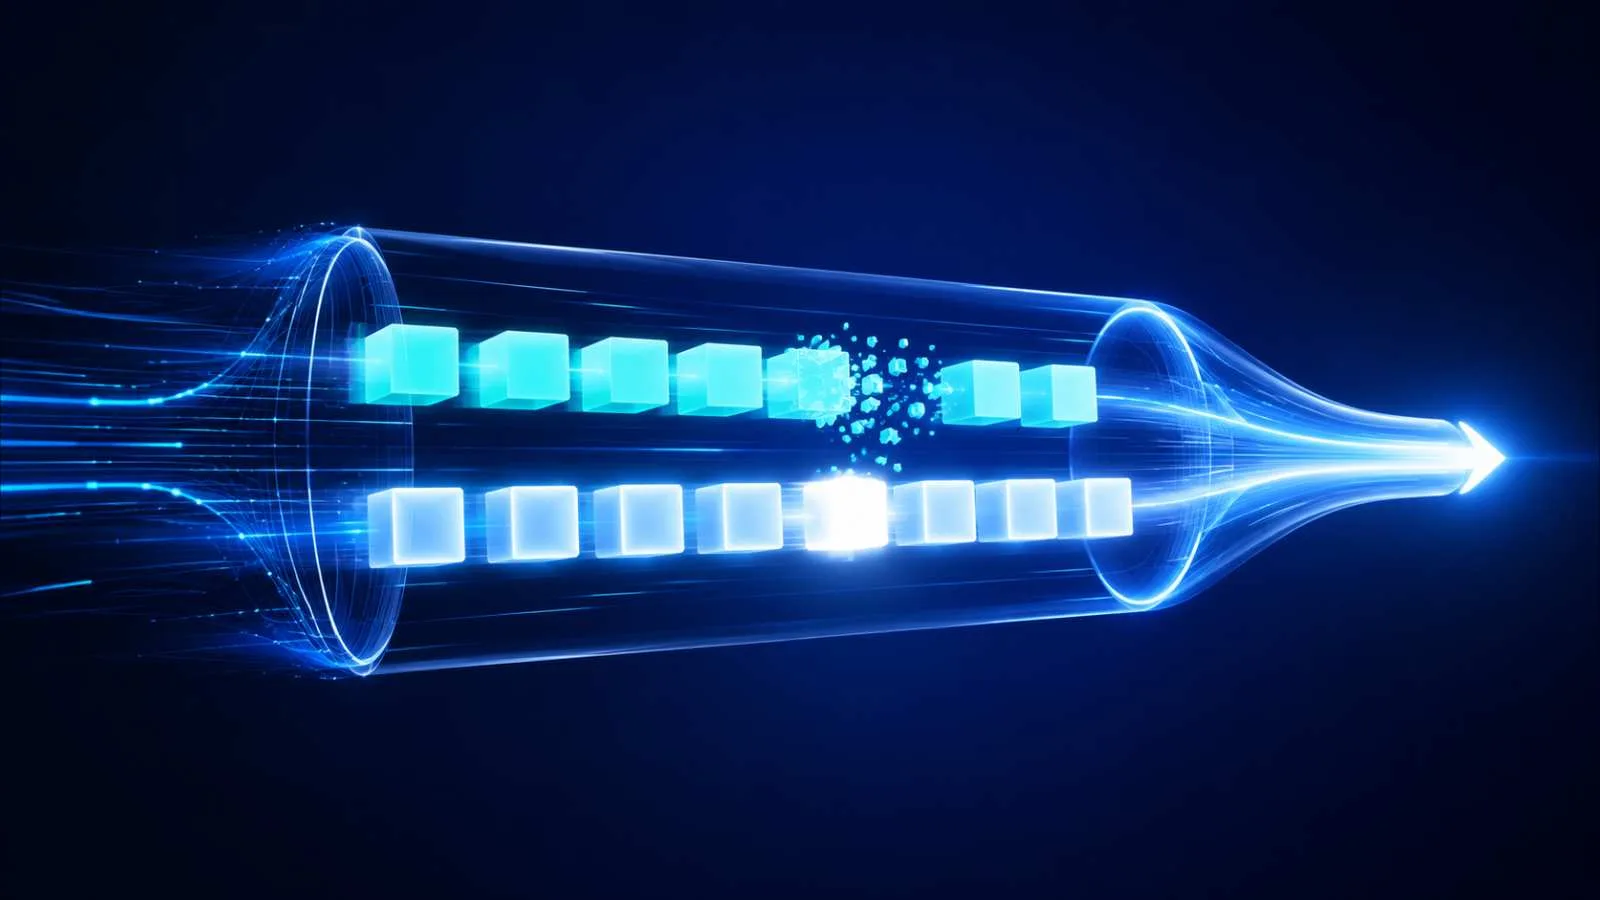
The process runs in two consecutive steps. First, the draft model generates a number of speculative tokens in the traditional autoregressive manner, for example four or five tokens in a row. Because the draft model is small, this step takes very little time. Next, these proposed tokens are presented to the large target model in a single pass.
Because the target model receives a sequence of tokens as input at once, it can process them in parallel, similar to the prefill phase of a prompt. The large model evaluates the probability of all proposed tokens in a single memory pass. If the proposals are correct, this yields multiple accepted tokens in the time of one large network pass.
Verification and acceptance without quality loss
A crucial requirement for speculative decoding is that the final text quality and the statistical distribution of the output remain exactly equal to the situation in which the large model would have generated all tokens independently. It must not function as an approximation that degrades the output.
To achieve this, the system applies a specific acceptance and rejection algorithm based on the probability distributions of both models. For each proposed token, the algorithm compares the probability the draft model assigned to the token with the probability the target model assigns to the same token.
Statistical equivalence: If the target model's probability for a proposed token is higher than or equal to the draft model's probability, the token is guaranteed to be accepted. If the target model's probability is lower, the token is accepted or rejected with a corrected probability.
When a token is rejected at a certain point in the speculative sequence, the verification process for the subsequent tokens in that sequence stops. The tokens already accepted up to the point of rejection are kept. At the position of the first rejected token, the target model immediately generates a new, corrected token from an adjusted probability distribution. As a result, no pass is wasted: the target model always produces at least one final token at every verification step, and multiple tokens when the acceptance rate is high.
Thanks to this mathematical correction, the end result is guaranteed to be identical to a direct sampling session with the target model. There is no quality loss or increased hallucination.
Factors that determine the efficiency gain
The actual time savings that can be achieved with speculative decoding depend on several variables in the system architecture and the context of the task.
| Factor | Influence on the process | Optimal condition |
|---|---|---|
| Acceptance rate | The percentage of proposed tokens approved by the target model. | High agreement in outcomes between the draft and target model. |
| Draft length (γ) | The number of tokens the draft model speculatively generates per cycle. | Tuned to the average acceptance probability (usually 3 to 6 tokens). |
| Speed difference | The ratio in latency between one step of the draft model and the target model. | A significantly smaller and faster draft model. |
When the acceptance rate is high, the system can process large amounts of text with just a few large network passes. If the draft model makes poor predictions, however, tokens must often be rejected. In that case, the process shifts toward the baseline speed of the target model, plus the minimal overhead of the draft model.
The chosen speculation length requires a balance. A sequence of speculative tokens that is too long costs extra time for the draft model. If the second or third token is already rejected, the compute time for the later tokens in the sequence is wasted. The chosen setting should therefore be tuned to the expected predictability of the generated text.
Variants and alternative approaches
In addition to the classic setup with two separate models, several variants of speculative decoding have been developed to increase applicability and efficiency.
Self-speculation (Self-speculative decoding)
With self-speculation, no separate small model is used. Instead, the target model has additional internal prediction heads on intermediate layers, or the model is temporarily instructed to skip certain layers. This allows the same model to make fast internal proposals and then verify them at full depth. This avoids the need to train and load a separate draft model.
Prompt and n-gram lookup
In situations where a lot of text is reproduced from the input context or from structured templates, the draft model can be replaced by a mechanism based on n-gram lookups. The system scans the text already present for recurring pattern sequences and uses these patterns as speculative proposals. This costs virtually no compute power and works effectively for tasks such as summarizing or rewriting documents.
Layered and tree-structure speculation
Advanced implementations do not generate a linear chain of tokens, but a tree structure of possible continuation paths. The target model then evaluates multiple branches simultaneously via special attention masks. This increases the chance that at least one valid path is among the proposals, which raises the effective acceptance rate per step.
When speculative decoding is less effective
Although the technique offers advantages in many scenarios, there are clear situations where its benefit is limited or can even cause a slowdown.
- Large batch sizes (high concurrency): Once a server processes dozens of requests simultaneously, the load on the hardware changes. Memory bandwidth is then optimally utilized because the target model's weights are applied to multiple input sequences at once (compute-bound). The need to reduce memory transfers largely disappears, so extra steps with a draft model only add overhead.
- Strongly divergent domains: If the draft model was trained on a general dataset and is deployed in a specific field (such as complex medical code or niche programming languages) in which the target model is specialized, the acceptance rate drops sharply. The target model will reject most proposals.
- High sampling temperature: At a high temperature setting, the randomness of the chosen tokens increases. This broadens the probability distribution and reduces the overlap between the probabilities of the draft and target model, which leads to a lower acceptance rate. More details on these settings can be found in the explanation of sampling parameters.
Relationship to other optimization techniques
Speculative decoding is a complementary technique within the spectrum of inference optimization methods. It does not replace other techniques, but addresses a specific problem left untouched by other methods.
For example, quantization changes RAM memory usage by lowering the precision of the weights. This reduces the amount of data that needs to be moved across the memory bus per step. Distillation permanently shrinks a model by transferring the knowledge of a large model to a smaller network. Speculative decoding, on the other hand, does not affect the parameters of the target model and retains full precision.
Furthermore, the use of a KV cache avoids duplicate calculations of historical tokens, and batching increases efficiency with multiple users. Speculative decoding operates at a higher level: it bundles multiple autoregressive steps for a single sequence into one pass of the main model, regardless of the quantization or caching applied.
When building applications for small models on devices with limited memory bandwidth, speculative decoding proves to be a valuable strategy for improving the processing speed of the generation process without compromising output quality.
Further reading
- Inference explained: The processing pipeline of language models
- Sampling parameters: Temperature, top-p, and top-k
- Distillation explained: Knowledge transfer to smaller models
- Parameters and weights in neural networks
- Quantization explained: Model precision and memory usage
- Small models on devices: Local inference challenges